点击上图,立即开启AI急速修炼
作者:Charlotte 高级算法工程师 ,博客专家;
擅长用通俗易懂的方式讲解深度学习和机器学习算法,熟悉Tensorflow,PaddlePaddle等深度学习框架,负责过多个机器学习落地项目,如垃圾评论自动过滤,用户分级精准营销,分布式深度学习平台搭建等,都取了的不错的效果。
博客专栏:https://www.cnblogs.com/charlotte77/
前文传送门:
【好书推荐&学习阶段】三个月教你从零入门深度学习
上周在搜索关于深度学习分布式运行方式的资料时,无意间搜到了paddlepaddle,发现这个框架的分布式训练方案做的还挺不错的,想跟大家分享一下。不过呢,这块内容太复杂了,所以就简单的介绍一下paddlepaddle的第一个“hello word”程序----mnist手写数字识别。下一次再介绍用PaddlePaddle做分布式训练的方案。其实之前也写过一篇用CNN识别手写数字集的文章(http://www.cnblogs.com/charlotte77/p/5671136.html),是用keras实现的,这次用了paddlepaddle后,正好可以简单对比一下两个框架的优劣。
什么是PaddlePaddle?
PaddlePaddle是百度推出的一个深度学习框架,可能大多数人平常用的比较多的一般是tensorflow,caffe,mxnet等,但其实PaddlePaddle也是一个非常不错的框架(据说以前叫Paddle,现在改名叫PaddlePaddle,不知道为啥总觉得有股莫名的萌点)
PaddlePaddle能做什么?
传统的基本都能做,尤其对NLP的支持很好,譬如情感分析,word embedding,语言模型等,反正你想得到的,常见的都可以用它来试一试~
PaddlePaddle的安装
不得不吐槽一下PaddlePaddle的安装,官网上说“PaddlePaddle目前唯一官方支持的运行的方式是Docker容器”,而docker其实在国内还并不是特别的流行,之前遇到的所有的框架,都有很多种安装方式,非常方便,所以这个唯一支持docker让人觉得非常诡异 = =!不过偶然试了一下,居然可以用pip install,不过为啥官网上没有写呢?所以,对于新手来说,最简单的安装方式就是:
pip install paddlepaddle
pip install paddlepaddle-gpu
用PaddlePaddle实现手写数字识别
训练步骤
传统的方式这次就不展开讲了,为了对比我们还是用CNN来进行训练。PaddlePaddle训练一次模型完整的过程可以如下几个步骤:
导入数据---->定义网络结构---->训练模型---->保存模型---->测试结果
下面,我直接用代码来展示训练的过程(以后代码都会放在github里):
https://github.com/huxiaoman7/PaddlePaddle_code
#coding:utf-8
import os
from PIL import Image
import numpy as np
import paddle.v2 as paddle

# 设置是否用gpu,0为否,1为是
with_gpu = os.getenv('WITH_GPU', '0') != '1'

# 定义网络结构
def convolutional_neural_network_org(img):
    # 第一层卷积层
    conv_pool_1 = paddle.networks.simple_img_conv_pool(
        input=img,
        filter_size=5,
        num_filters=20,
        num_channel=1,
        pool_size=2,
        pool_stride=2,
        act=paddle.activation.Relu())
    # 第二层卷积层
    conv_pool_2 = paddle.networks.simple_img_conv_pool(
        input=conv_pool_1,
        filter_size=5,
        num_filters=50,
        num_channel=20,
        pool_size=2,
        pool_stride=2,
        act=paddle.activation.Relu())
    # 全连接层
    predict = paddle.layer.fc(
        input=conv_pool_2, size=10, act=paddle.activation.Softmax())
    return predict

def main():
    # 初始化定义跑模型的设备
    paddle.init(use_gpu=with_gpu, trainer_count=1)

    # 读取数据
    images = paddle.layer.data(
        name='pixel', type=paddle.data_type.dense_vector(784))
    label = paddle.layer.data(
        name='label', type=paddle.data_type.integer_value(10))

    # 调用之前定义的网络结构
    predict = convolutional_neural_network_org(images)

    # 定义损失函数
    cost = paddle.layer.classification_cost(input=predict, label=label)

    # 指定训练相关的参数
    parameters = paddle.parameters.create(cost)

    # 定义训练方法
    optimizer = paddle.optimizer.Momentum(
        learning_rate=0.1 / 128.0,
        momentum=0.9,
        regularization=paddle.optimizer.L2Regularization(rate=0.0005 * 128))

    # 训练模型
    trainer = paddle.trainer.SGD(
        cost=cost, parameters=parameters, update_equation=optimizer)


    lists = []

    # 定义event_handler,输出训练过程中的结果
    def event_handler(event):
        if isinstance(event, paddle.event.EndIteration):
            if event.batch_id % 100 == 0:
                print "Pass %d, Batch %d, Cost %f, %s" % (
                    event.pass_id, event.batch_id, event.cost, event.metrics)
        if isinstance(event, paddle.event.EndPass):
            # 保存参数
            with open('params_pass_%d.tar' % event.pass_id, 'w') as f:
                parameters.to_tar(f)

            result = trainer.test(reader=paddle.batch(
                paddle.dataset.mnist.test(), batch_size=128))
            print "Test with Pass %d, Cost %f, %s\n" % (
                event.pass_id, result.cost, result.metrics)
            lists.append((event.pass_id, result.cost,
                          result.metrics['classification_error_evaluator']))

    trainer.train(
        reader=paddle.batch(
            paddle.reader.shuffle(paddle.dataset.mnist.train(), buf_size=8192),
            batch_size=128),
        event_handler=event_handler,
        num_passes=10)

    # 找到训练误差最小的一次结果
    best = sorted(lists, key=lambda list: float(list[1]))[0]
    print 'Best pass is %s, testing Avgcost is %s' % (best[0], best[1])
    print 'The classification accuracy is %.2f%%' % (100 - float(best[2]) * 100)

    # 加载数据
    def load_image(file):
        im = Image.open(file).convert('L')
        im = im.resize((28, 28), Image.ANTIALIAS)
        im = np.array(im).astype(np.float32).flatten()
        im = im / 255.0
        return im

    # 测试结果
    test_data = []
    cur_dir = os.path.dirname(os.path.realpath(__file__))
    test_data.append((load_image(cur_dir + '/image/infer_3.png'), ))

    probs = paddle.infer(
        output_layer=predict, parameters=parameters, input=test_data)
    lab = np.argsort(-probs)  # probs and lab are the results of one batch data
    print "Label of image/infer_3.png is: %d" % lab[0][0]


if __name__ == '__main__':
    main()
上面的代码看起来很长,但结构还是很清楚的。下面我们用实际数据测试一下,看一下效果到底怎么样~
BaseLine版本
首先我用了官网给出的例子,直接用最基本的CNN网络结构训练了一下,代码如下:
def convolutional_neural_network_org(img):
# 第一层卷积层
conv_pool_1 = paddle.networks.simple_img_conv_pool(
input=img,
filter_size=5,
num_filters=20,
num_channel=1,
pool_size=2,
pool_stride=2,
act=paddle.activation.Relu())
# 第二层卷积层
conv_pool_2 = paddle.networks.simple_img_conv_pool(
input=conv_pool_1,
filter_size=5,
num_filters=50,
num_channel=20,
pool_size=2,
pool_stride=2,
act=paddle.activation.Relu())
# 全连接层
predict = paddle.layer.fc(
input=conv_pool_2, size=10, act=paddle.activation.Softmax())
return predict 输出结果如下:
I1023 13:45:46.519075 34144 Util.cpp:166] commandline:  --use_gpu=True --trainer_count=1
[INFO 2017-10-23 13:45:52,667 layers.py:2539] output for __conv_pool_0___conv: c = 20, h = 24, w = 24, size = 11520
[INFO 2017-10-23 13:45:52,667 layers.py:2667] output for __conv_pool_0___pool: c = 20, h = 12, w = 12, size = 2880
[INFO 2017-10-23 13:45:52,668 layers.py:2539] output for __conv_pool_1___conv: c = 50, h = 8, w = 8, size = 3200
[INFO 2017-10-23 13:45:52,669 layers.py:2667] output for __conv_pool_1___pool: c = 50, h = 4, w = 4, size = 800
I1023 13:45:52.675750 34144 GradientMachine.cpp:85] Initing parameters..
I1023 13:45:52.686153 34144 GradientMachine.cpp:92] Init parameters done.
Pass 0, Batch 0, Cost 3.048408, {'classification_error_evaluator': 0.890625}
Pass 0, Batch 100, Cost 0.188828, {'classification_error_evaluator': 0.0546875}
Pass 0, Batch 200, Cost 0.075183, {'classification_error_evaluator': 0.015625}
Pass 0, Batch 300, Cost 0.070798, {'classification_error_evaluator': 0.015625}
Pass 0, Batch 400, Cost 0.079673, {'classification_error_evaluator': 0.046875}
Test with Pass 0, Cost 0.074587, {'classification_error_evaluator': 0.023800000548362732}
```
```
```
Pass 4, Batch 0, Cost 0.032454, {'classification_error_evaluator': 0.015625}
Pass 4, Batch 100, Cost 0.021028, {'classification_error_evaluator': 0.0078125}
Pass 4, Batch 200, Cost 0.020458, {'classification_error_evaluator': 0.0}
Pass 4, Batch 300, Cost 0.046728, {'classification_error_evaluator': 0.015625}
Pass 4, Batch 400, Cost 0.030264, {'classification_error_evaluator': 0.015625}
Test with Pass 4, Cost 0.035841, {'classification_error_evaluator': 0.01209999993443489}

Best pass is 4, testing Avgcost is 0.0358410408473
The classification accuracy is 98.79%
Label of image/infer_3.png is: 3

real    0m31.565s
user    0m20.996s
sys    0m15.891s
可以看到,第一行输出选择的设备是否是gpu,这里我选择的是gpu,所以等于1,如果是cpu,就是0。接下来四行输出的是网络结构,然后开始输出训练结果,训练结束,我们把这几次迭代中误差最小的结果输出来,98.79%,效果还是很不错的,毕竟只迭代了5次。最后看一下输出时间,非常快,约31秒。然而这个结果我并不是特别满意,因为之前用keras做的时候调整的网络模型训练往后准确率能够达到99.72%,不过速度非常慢,迭代69次大概需要30分钟左右,所以我觉得这个网络结构还是可以改进一下的,所以我对这个网络结构改进了一下,请看改进版
改进版
def convolutional_neural_network(img):
    # 第一层卷积层
    conv_pool_1 = paddle.networks.simple_img_conv_pool(
        input=img,
        filter_size=5,
        num_filters=20,
        num_channel=1,
        pool_size=2,
        pool_stride=2,
        act=paddle.activation.Relu())
    # 加一层dropout层
    drop_1 = paddle.layer.dropout(input=conv_pool_1, dropout_rate=0.2)
    # 第二层卷积层
    conv_pool_2 = paddle.networks.simple_img_conv_pool(
        input=drop_1,
        filter_size=5,
        num_filters=50,
        num_channel=20,
        pool_size=2,
        pool_stride=2,
        act=paddle.activation.Relu())
    # 加一层dropout层
    drop_2 = paddle.layer.dropout(input=conv_pool_2, dropout_rate=0.5)
    # 全连接层
    fc1 = paddle.layer.fc(input=drop_2, size=10, act=paddle.activation.Linear())
    bn = paddle.layer.batch_norm(input=fc1,act=paddle.activation.Relu(),
         layer_attr=paddle.attr.Extra(drop_rate=0.2))
    predict = paddle.layer.fc(input=bn, size=10, act=paddle.activation.Softmax())
    return predict
在改进版里我们加了一些dropout层来避免过拟合。分别在第一层卷积层和第二层卷积层后加了dropout,阈值设为0.5。改变网络结构也非常简单,直接在定义的网络结构函数里对模型进行修改即可,这一点其实和keras的网络结构定义方式还是挺像的,易用性很高。下面来看看效果:
I1023 14:01:51.653827 34244 Util.cpp:166] commandline:  --use_gpu=True --trainer_count=1
[INFO 2017-10-23 14:01:57,830 layers.py:2539] output for __conv_pool_0___conv: c = 20, h = 24, w = 24, size = 11520
[INFO 2017-10-23 14:01:57,831 layers.py:2667] output for __conv_pool_0___pool: c = 20, h = 12, w = 12, size = 2880
[INFO 2017-10-23 14:01:57,832 layers.py:2539] output for __conv_pool_1___conv: c = 50, h = 8, w = 8, size = 3200
[INFO 2017-10-23 14:01:57,833 layers.py:2667] output for __conv_pool_1___pool: c = 50, h = 4, w = 4, size = 800
I1023 14:01:57.842871 34244 GradientMachine.cpp:85] Initing parameters..
I1023 14:01:57.854014 34244 GradientMachine.cpp:92] Init parameters done.
Pass 0, Batch 0, Cost 2.536199, {'classification_error_evaluator': 0.875}
Pass 0, Batch 100, Cost 1.668236, {'classification_error_evaluator': 0.515625}
Pass 0, Batch 200, Cost 1.024846, {'classification_error_evaluator': 0.375}
Pass 0, Batch 300, Cost 1.086315, {'classification_error_evaluator': 0.46875}
Pass 0, Batch 400, Cost 0.767804, {'classification_error_evaluator': 0.25}
Pass 0, Batch 500, Cost 0.545784, {'classification_error_evaluator': 0.1875}
Pass 0, Batch 600, Cost 0.731662, {'classification_error_evaluator': 0.328125}
```
```
```
Pass 49, Batch 0, Cost 0.415184, {'classification_error_evaluator': 0.09375}
Pass 49, Batch 100, Cost 0.067616, {'classification_error_evaluator': 0.0}
Pass 49, Batch 200, Cost 0.161415, {'classification_error_evaluator': 0.046875}
Pass 49, Batch 300, Cost 0.202667, {'classification_error_evaluator': 0.046875}
Pass 49, Batch 400, Cost 0.336043, {'classification_error_evaluator': 0.140625}
Pass 49, Batch 500, Cost 0.290948, {'classification_error_evaluator': 0.125}
Pass 49, Batch 600, Cost 0.223433, {'classification_error_evaluator': 0.109375}
Pass 49, Batch 700, Cost 0.217345, {'classification_error_evaluator': 0.0625}
Pass 49, Batch 800, Cost 0.163140, {'classification_error_evaluator': 0.046875}
Pass 49, Batch 900, Cost 0.203645, {'classification_error_evaluator': 0.078125}
Test with Pass 49, Cost 0.033639, {'classification_error_evaluator': 0.008100000210106373}

Best pass is 48, testing Avgcost is 0.0313018567383
The classification accuracy is 99.28%
Label of image/infer_3.png is: 3

real    5m3.151s
user    4m0.052s
sys    1m8.084s
从上面的数据来看,这个效果还是很不错滴,对比之前用keras训练的效果来看,结果如下:
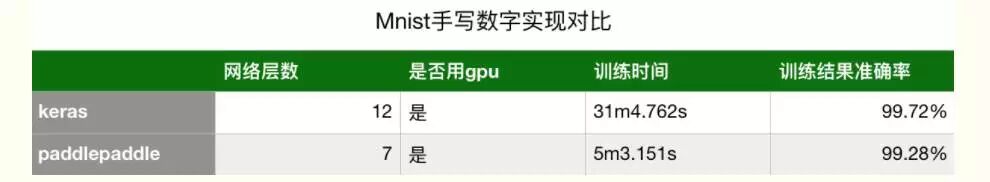
可以看到这个速度差异是很大的了,在准确率差不多的情况下,训练时间几乎比原来缩短了六倍,网络结构也相对简单,说明需要调整的参数也少了很多。
总结
paddlepaddle用起来还是很方便的,不论是定义网络结构还是训练速度,都值得一提,然而我个人的体验中,认为最值得说的是这几点:
1.导入数据方便。这次训练的手写数字识别数据量比较小,但是如果想要添加数据,也非常方便,直接添加到相应目录下。
2.event_handler机制,可以自定义训练结果输出内容。之前用的keras,以及mxnet等都是已经封装好的函数,输出信息都是一样的,这里paddlepaddle把这个函数并没有完全封装,而是让我们用户自定义输出的内容,可以方便我们减少冗余的信息,增加一些模型训练的细节的输出,也可以用相应的函数画出模型收敛的图片,可视化收敛曲线。
3.速度快。上面的例子已经证明了paddlepaddle的速度,并且在提升速度的同时,模型准确度也与最优结果相差不多,这对于我们训练海量数据的模型是一个极大的优势啊!
然而,paddlepaddle也有几点让我用的有点难受,譬如文档太少了啊,报错了上网上搜没啥结果啊等等,不过我觉得这个应该不是大问题,以后用的人多了以后肯定相关资料也会更多。所以一直很疑惑,为啥paddlepaddle不火呢?安装诡异是一个吐槽点,但其实还是很优秀的一个开源软件,尤其是最值得说的分布式训练方式,多机多卡的设计是非常优秀的,本篇没有讲,下次讲讲如何用paddlepaddle做单机单卡,单机多卡,多机单卡和多机多卡的训练方式来训练模型,大家多多用起来呀~~可以多交流呀~
ps:由于paddlepaddle的文档实在太少了,官网的文章理论介绍的比较多,网上的博文大多数都是几个经典例子来回跑,所以我打算写个系列,跟实战相关的,不再只有深度学习的“hello world”程序,这次用“hello world”做个引子,下篇开始写点干货哈哈~
想从零开始学人工智能?
下图扫码了解本文作者胡老师的系列课程吧!
限时优惠价299!